Get TurboLLM
on your own computerphone
One download, the whole stack inside — runtime, inference daemon and web UI. Windows, macOS and Linux installers, and Android from the Play Store. Free, no account, and nothing you type ever leaves your device.
Pick your platform
Windows, macOS and Linux are direct downloads today. Android installs straight from the Play Store.
macOS
DownloadUnsigned — macOS says "TurboLLM is damaged" on first launch. Open Terminal and run xattr -cr /Applications/TurboLLM.app, then open it again.
iOS
Join the iOS listNo build exists yet. Leave your email and you get one message when there is one.
One download. The whole stack inside.
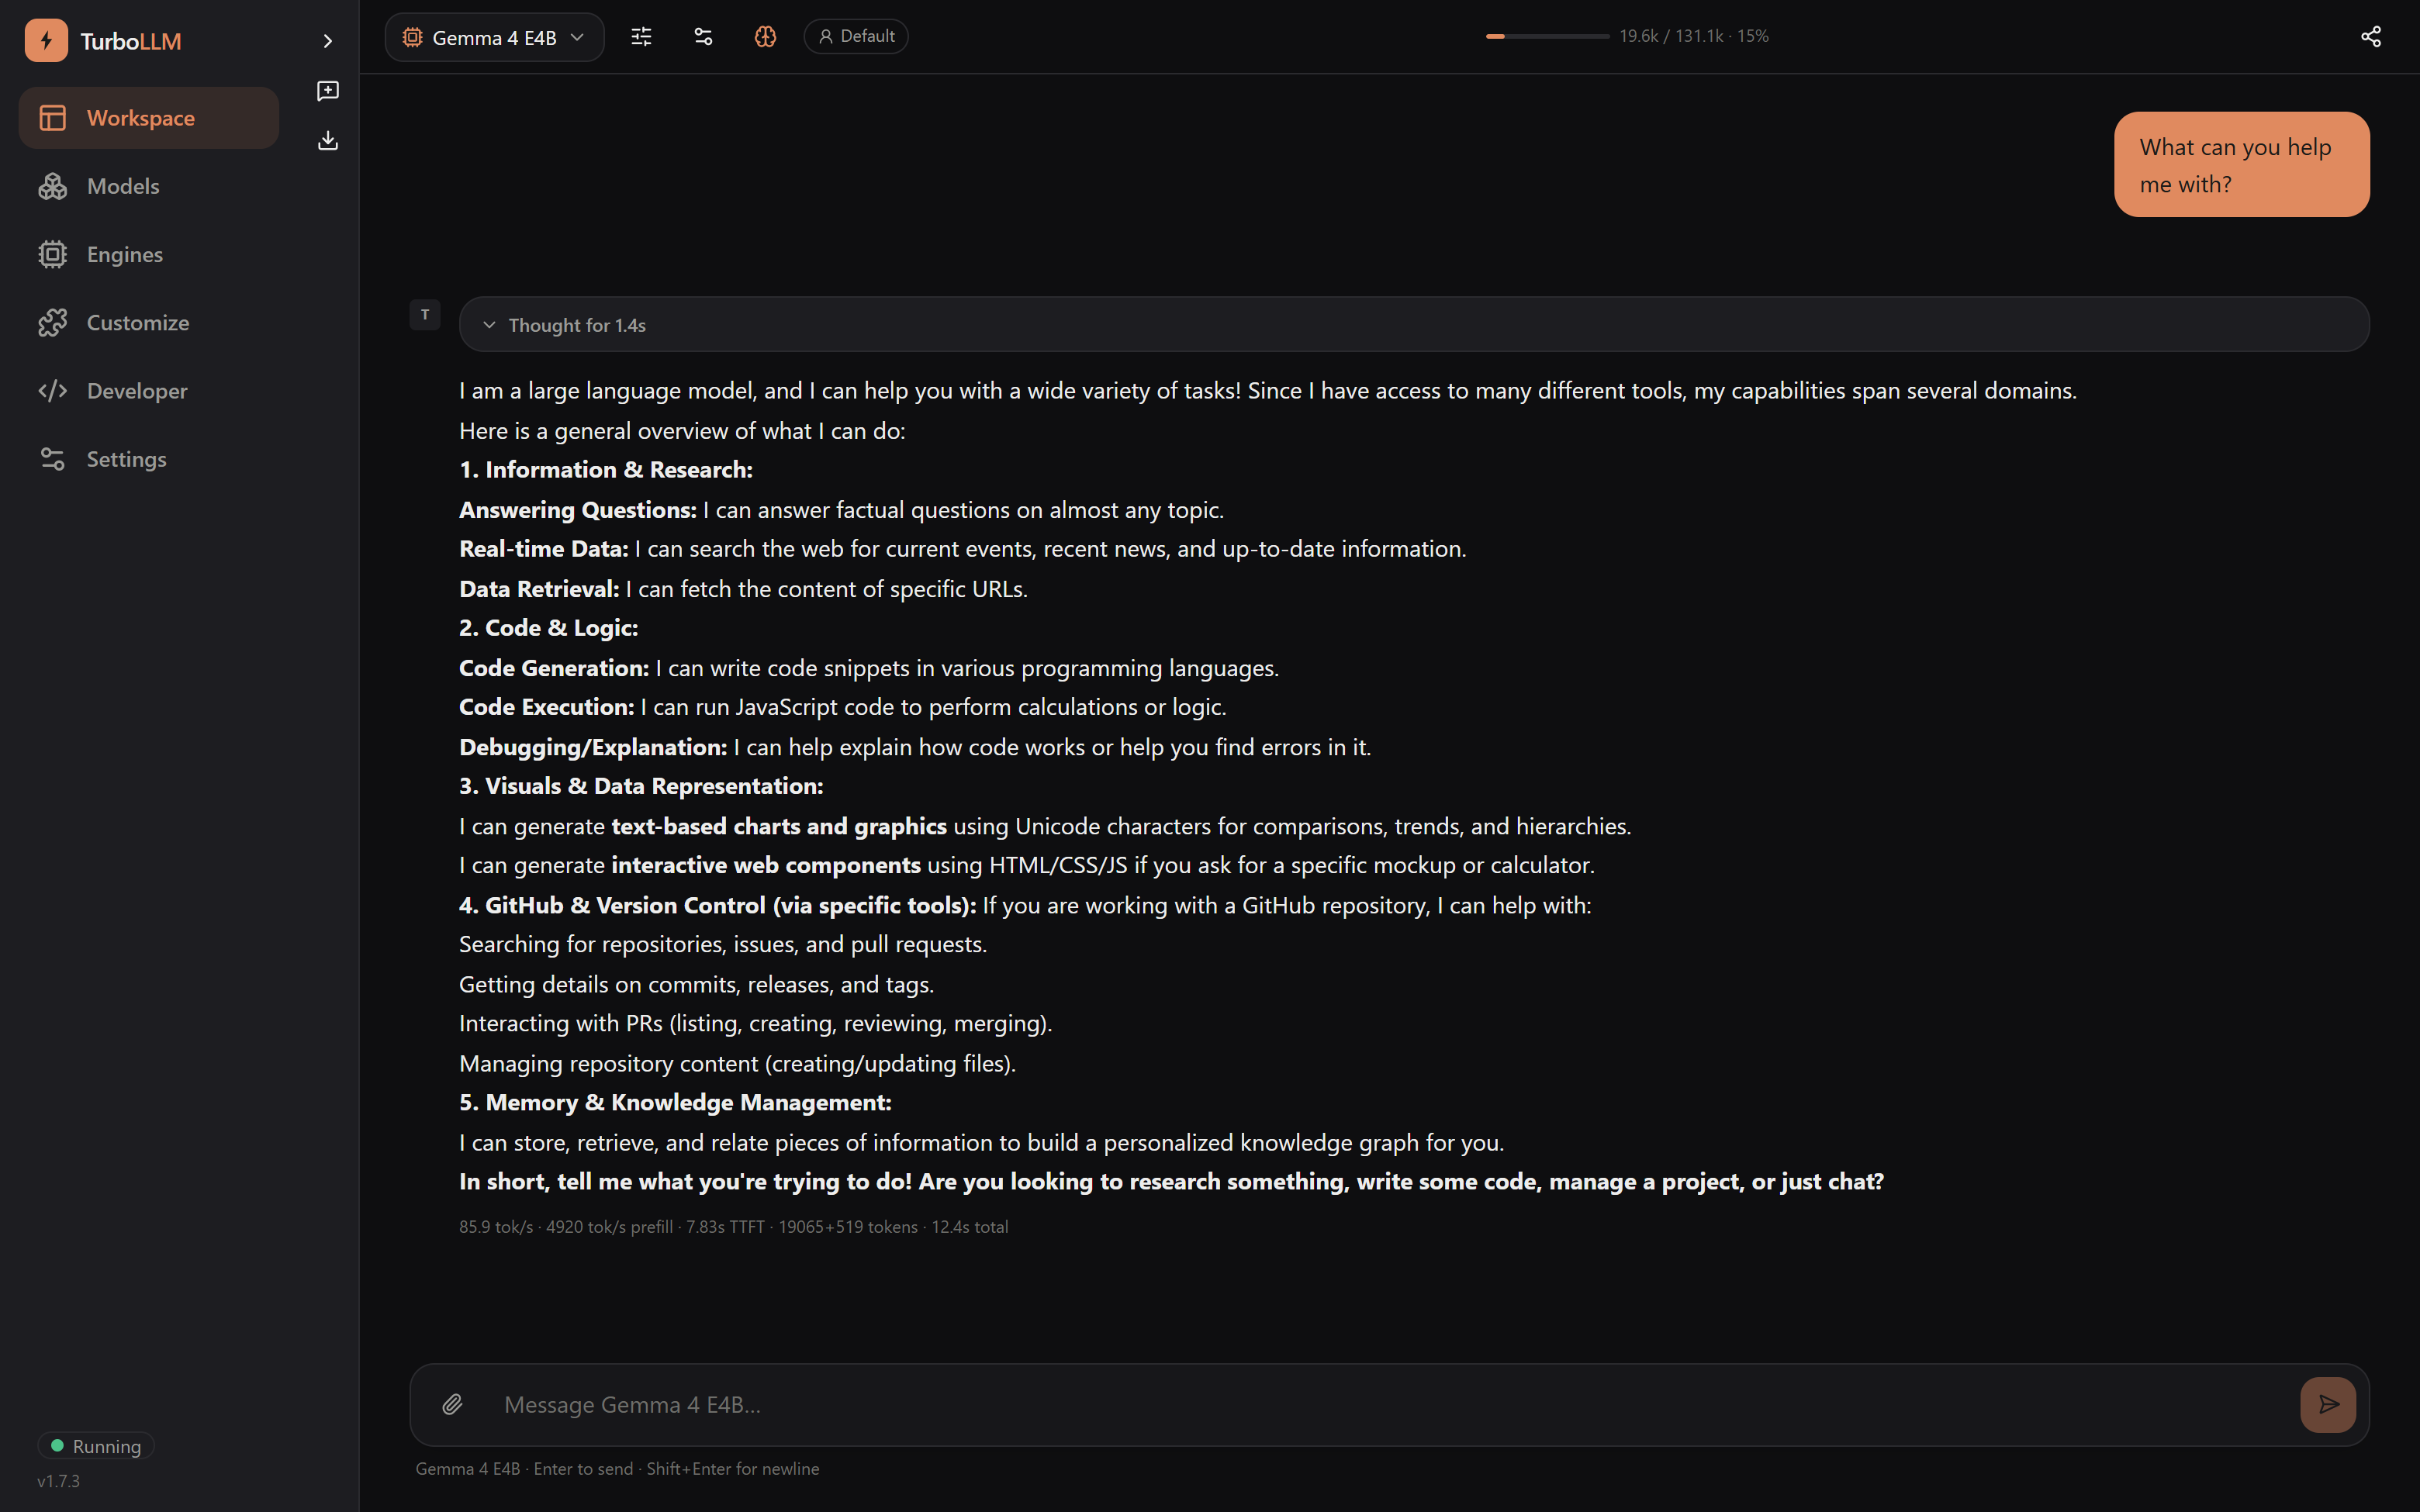
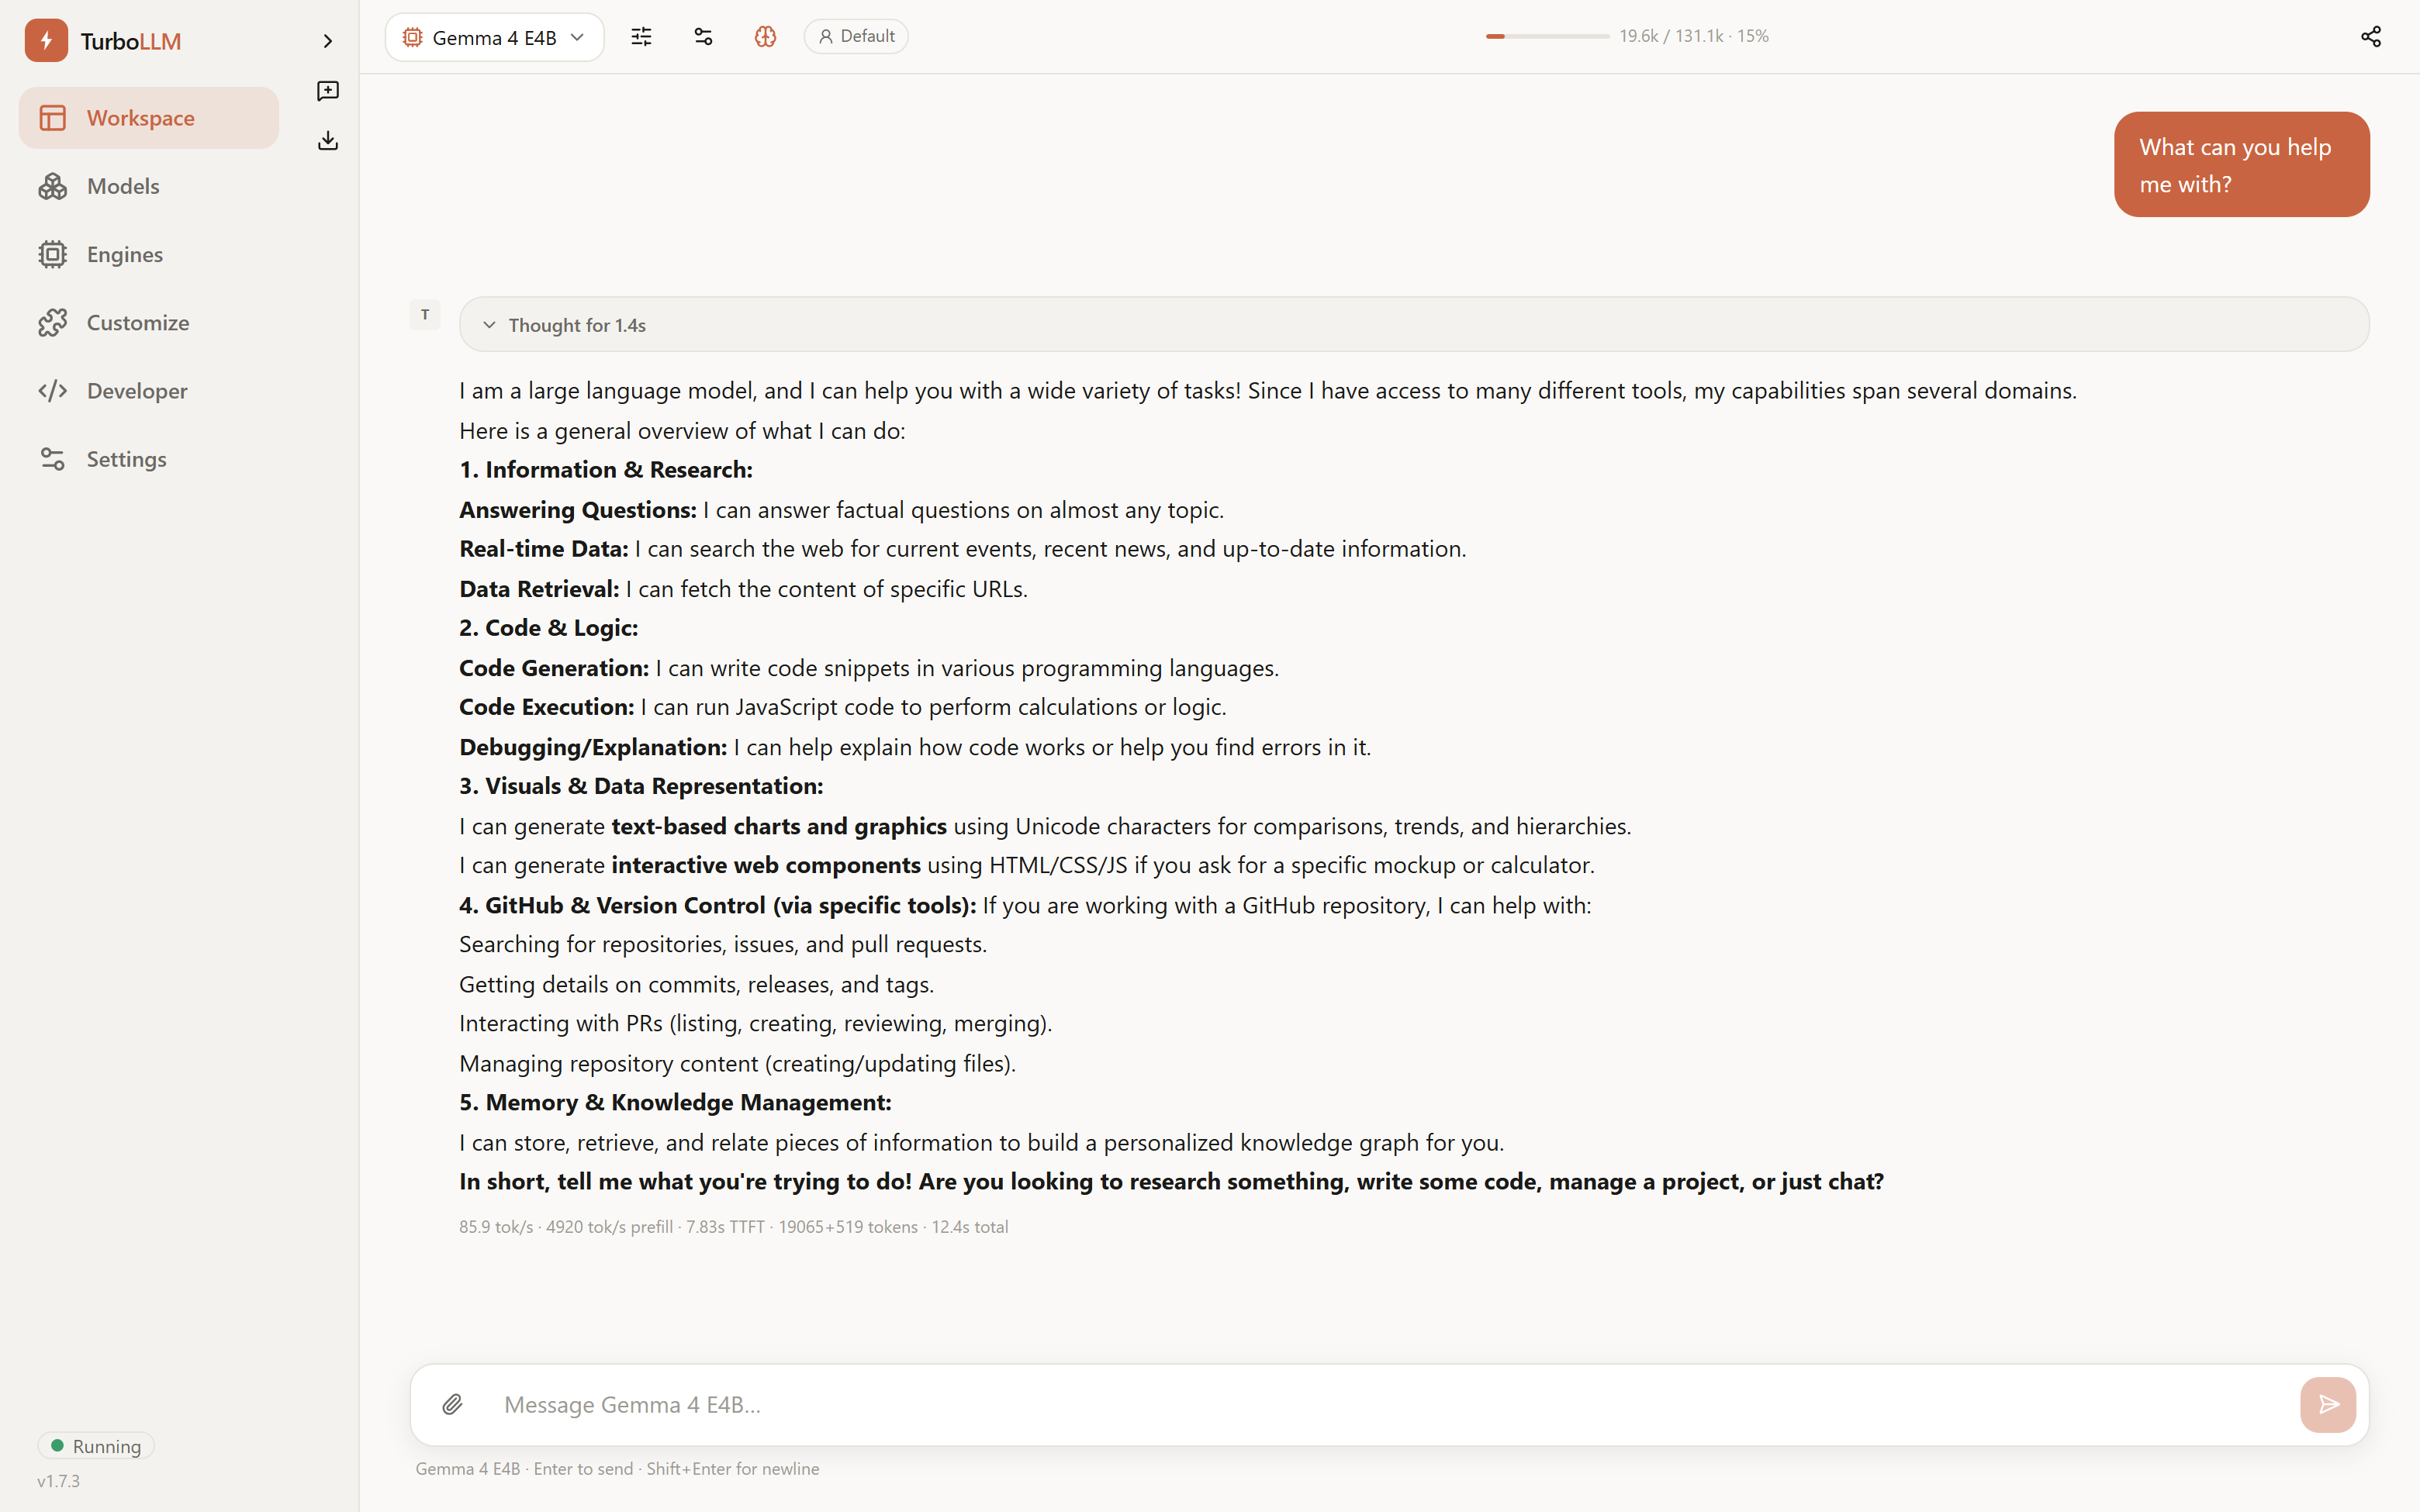
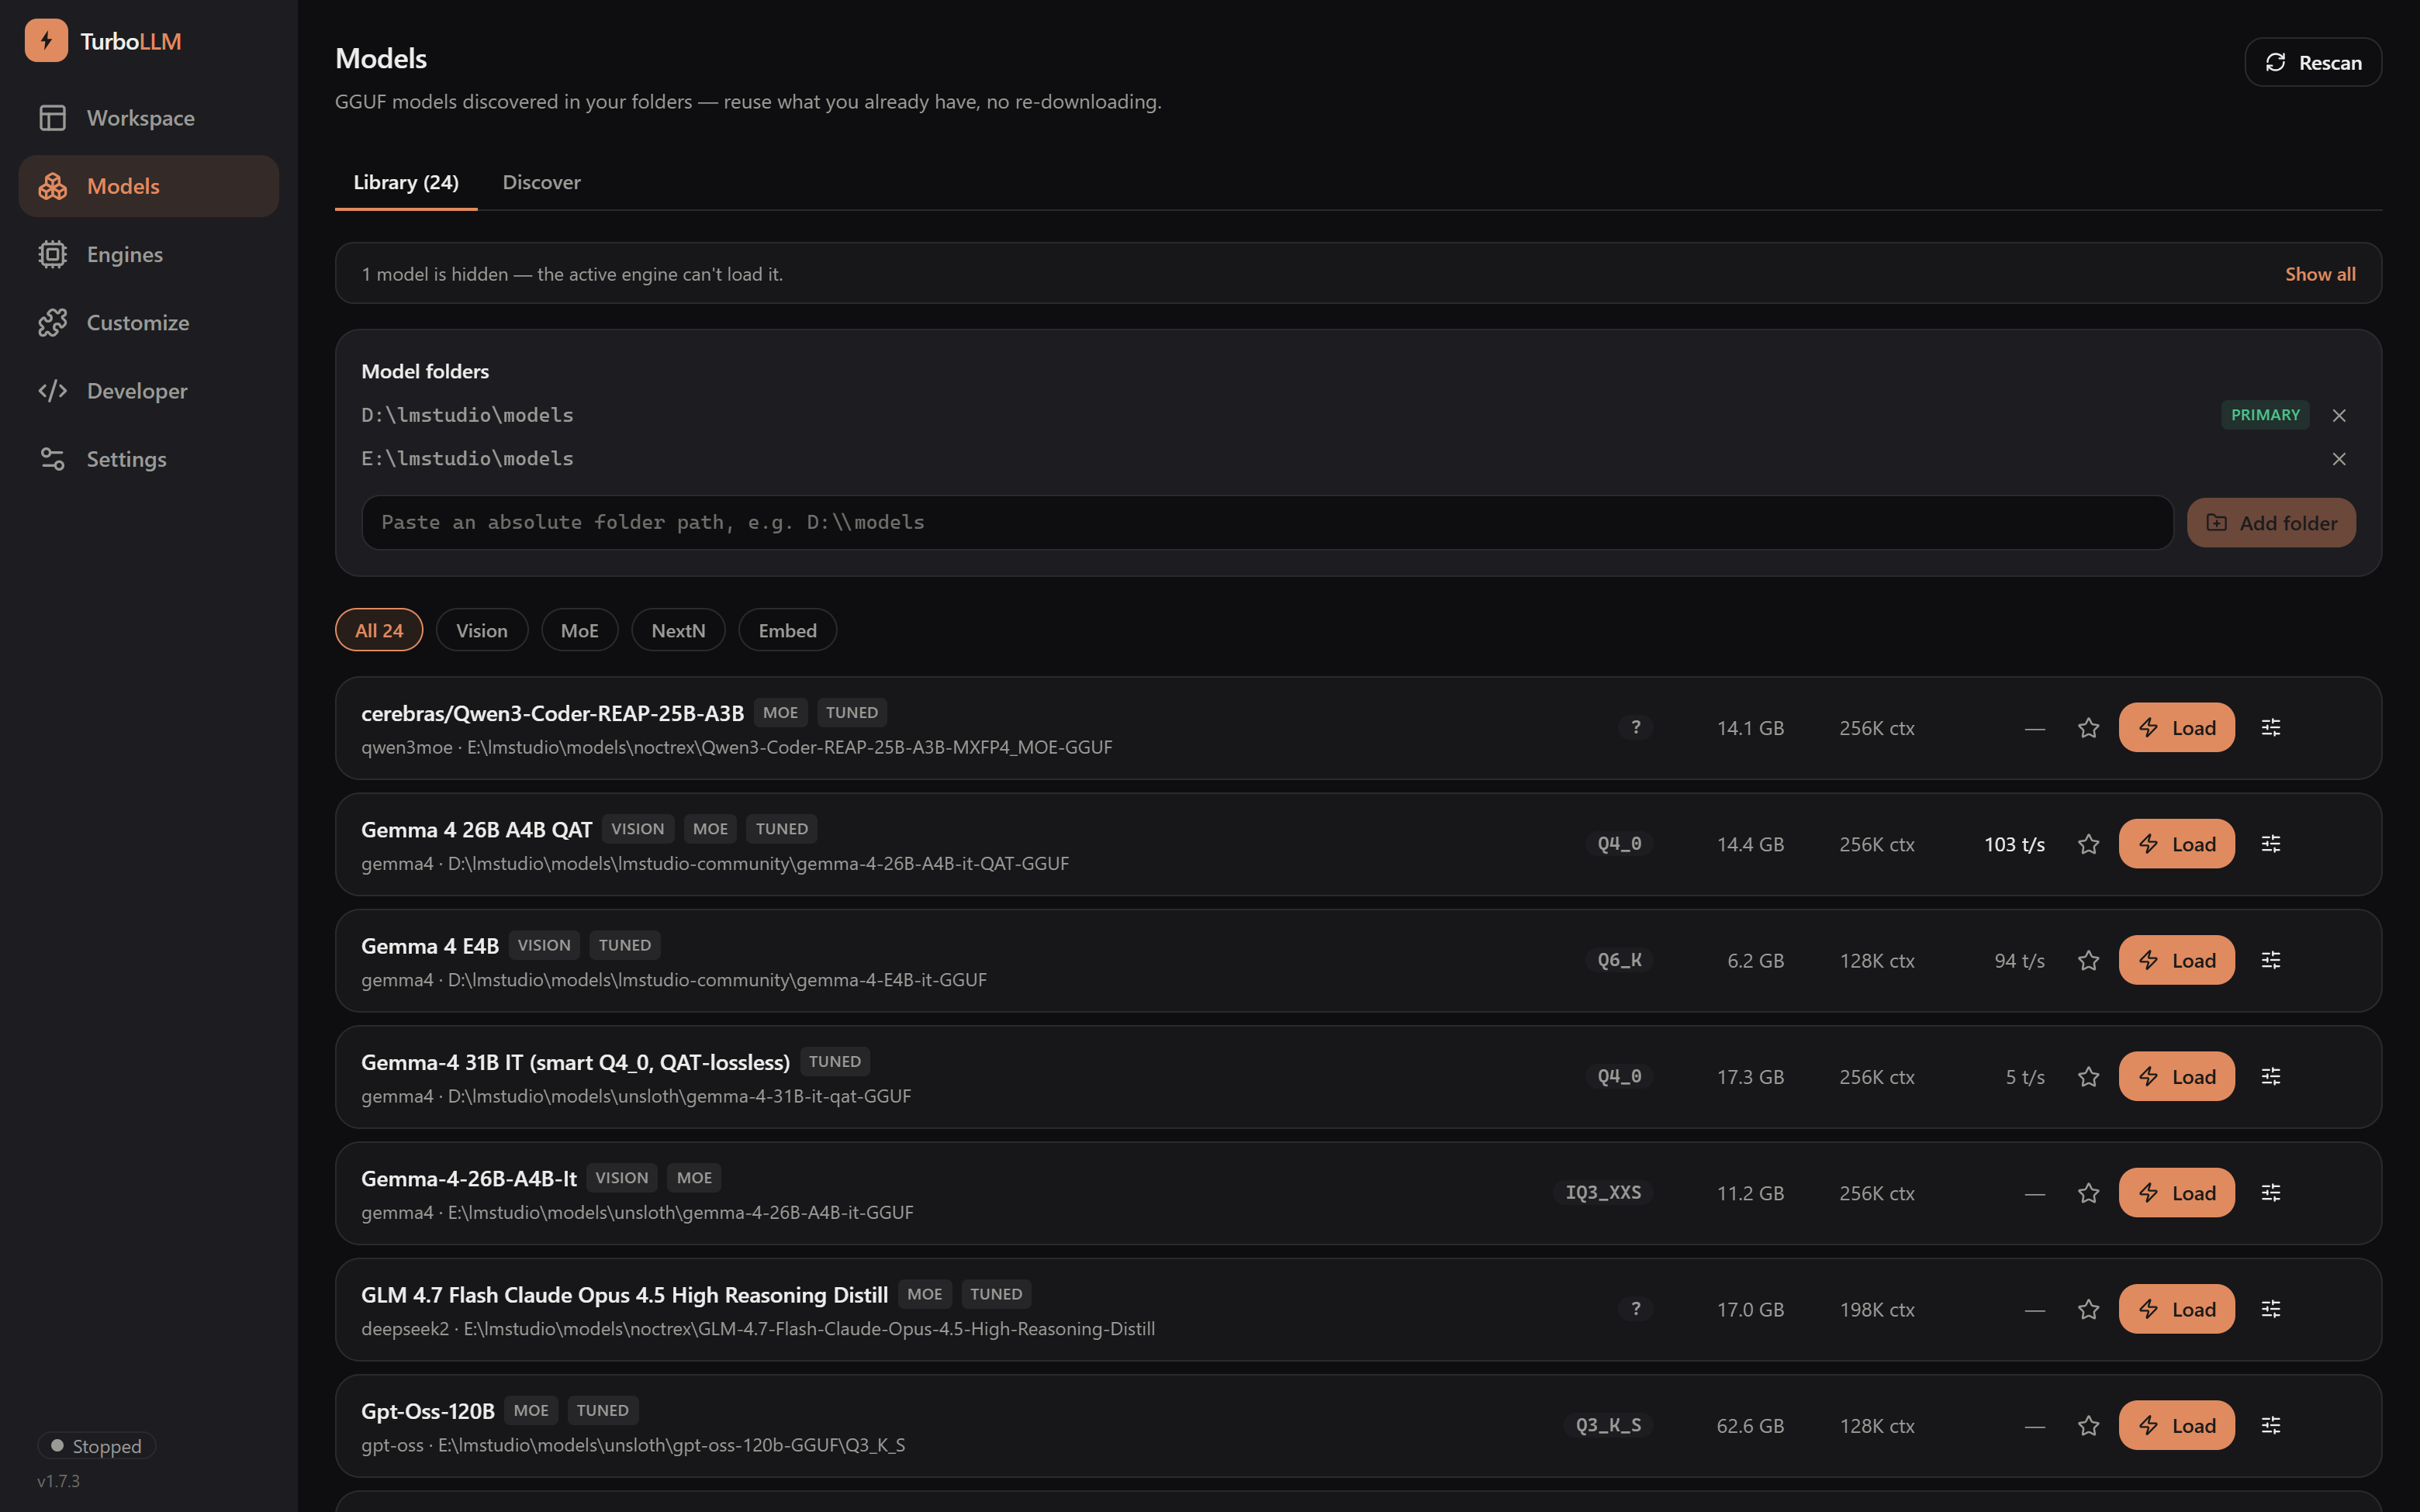
Runtime, inference daemon, model browser and web UI, all in a single installer. Download a model from Hugging Face without leaving the app, and it's auto-tuned to your GPU before the first token.
0
Accounts. Logins. Cloud calls.
Nothing to sign up for, nothing to subscribe to, nowhere for your prompts to go. Pull the network cable and it keeps working.
2.2×
Faster than the usual runners
Because it picks the right engine and the right flags for your hardware instead of one safe default for everybody.
Nothing to install first
No Node, no Python, no PATH surprises, no compiler. The installer brings its own runtime and the app updates itself from there.
Your files stay your files
Models, chats and settings live in one folder on your own disk. Nothing is held in an account, so you can back it up, move it, or delete it yourself.
Still any engine you want
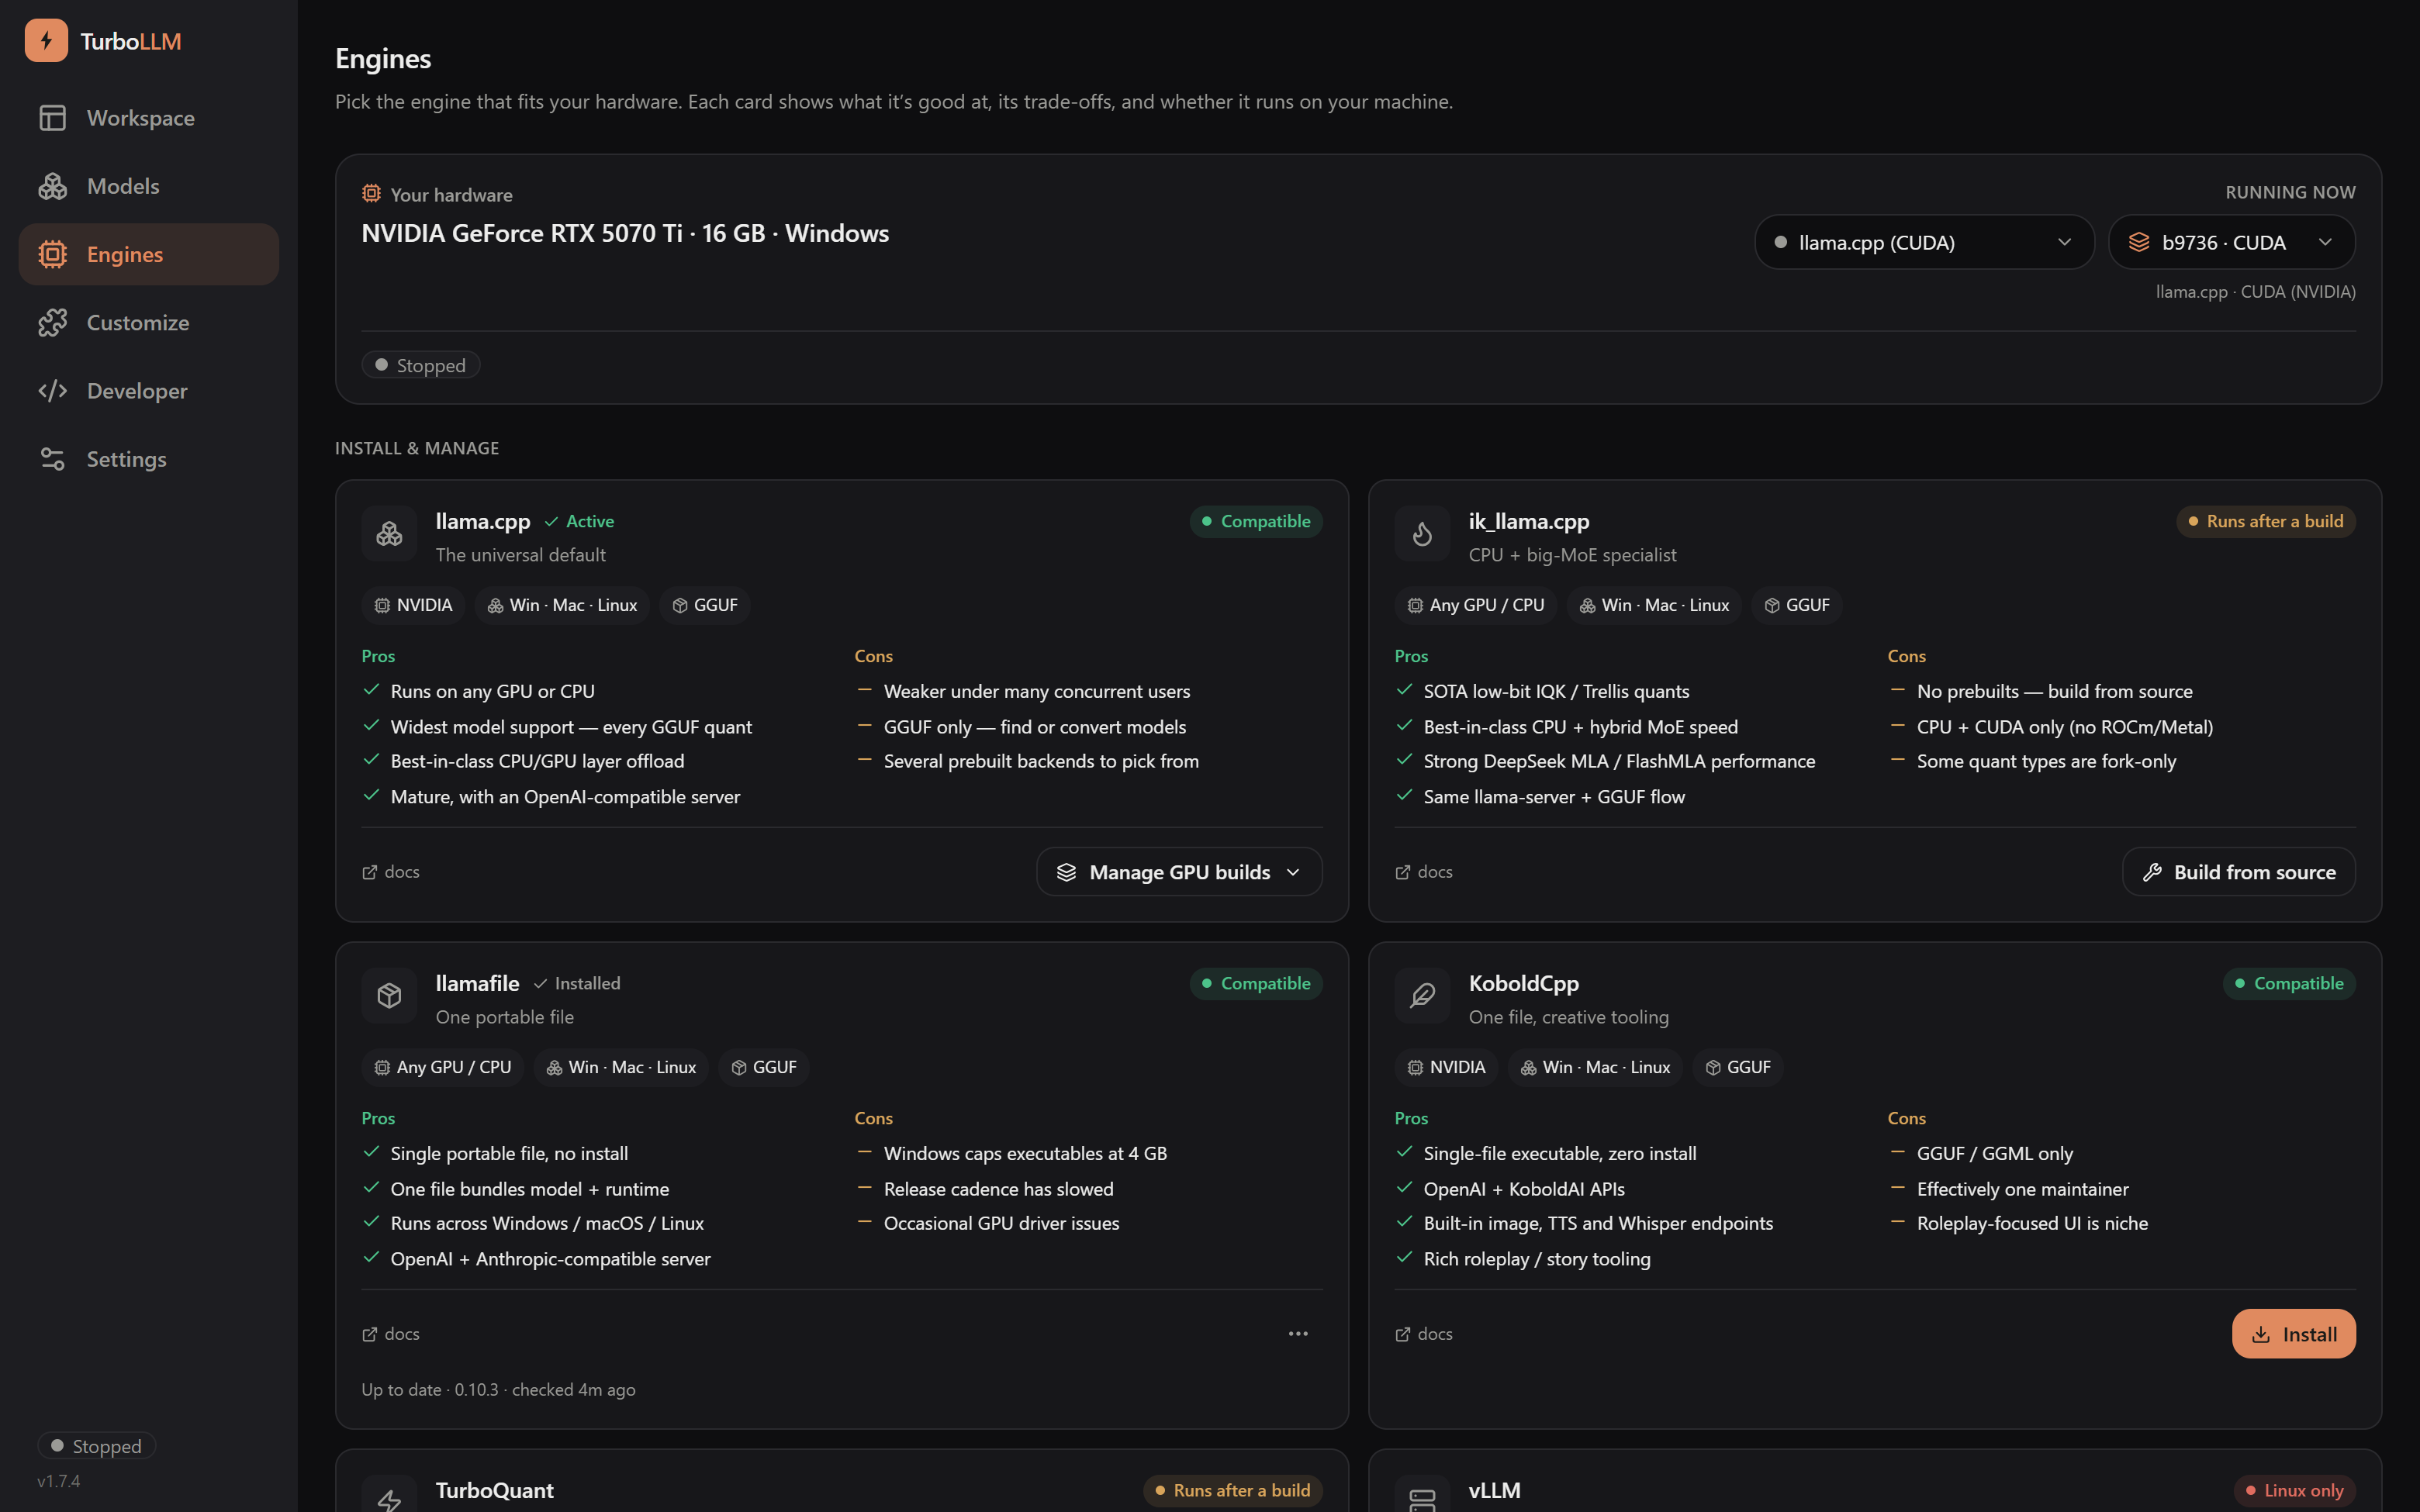
llama.cpp, ik_llama.cpp, TurboQuant, KoboldCpp, llamafile, MLX, vLLM — or a community fork nobody has packaged yet. Built for you, in-app.
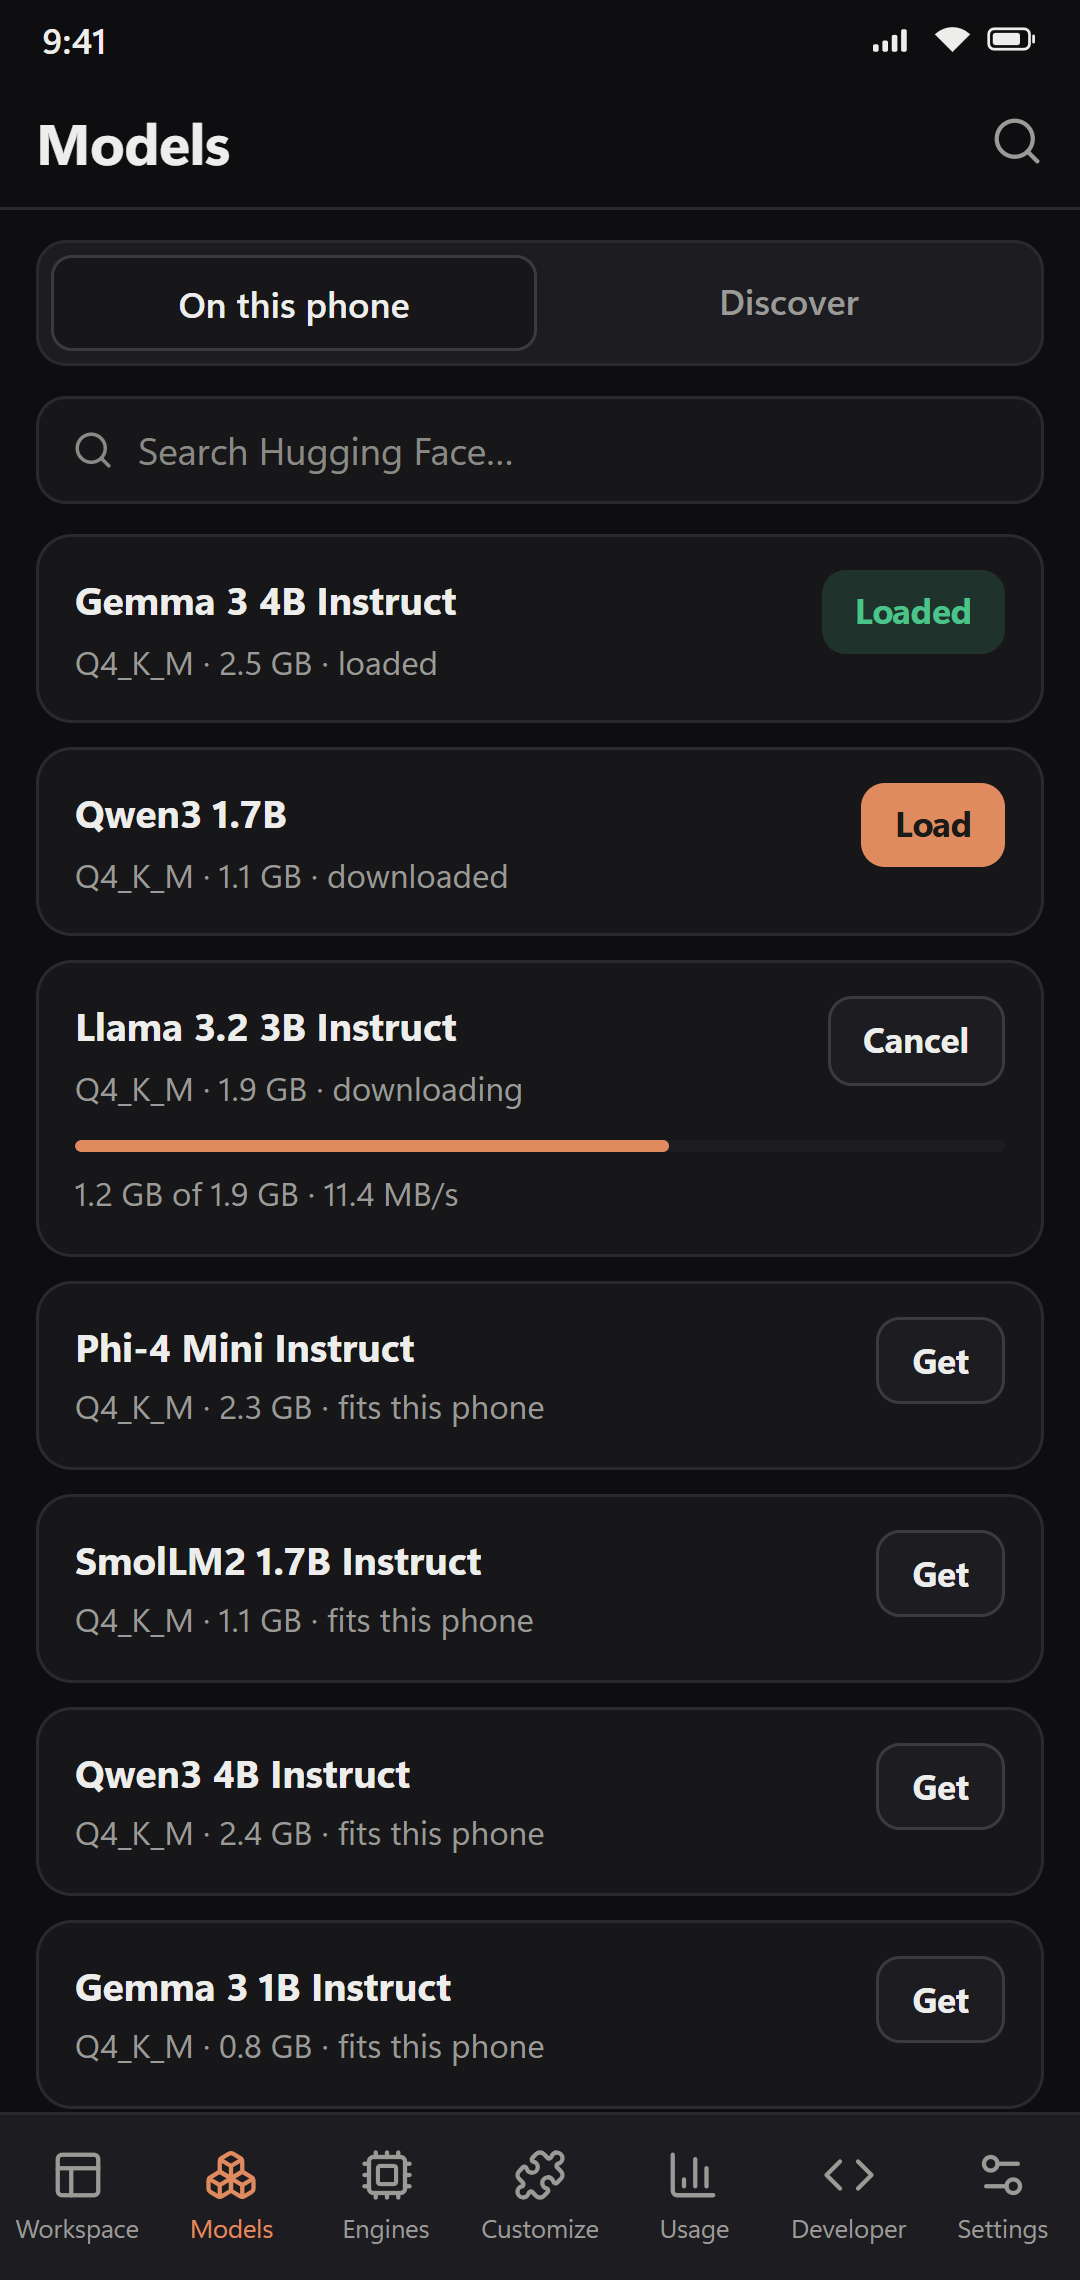
And a real model in your pocket
The Android app bundles the inference engine and runs the model on your phone's own CPU or GPU. Not a wrapper around someone's API — actual local inference, offline, on a phone.
Before you install, the unglamorous part
None of this is a reason to stay away. It's the stuff you'd otherwise discover at the worst possible moment.
None of the builds are signed
Windows shows a SmartScreen warning — click More info → Run anyway. macOS
says the app "is damaged" — that's Gatekeeper flagging the missing signature, not
real corruption; run xattr -cr /Applications/TurboLLM.app in Terminal
and it opens fine. Signing certificates cost real money every year and that call
hasn't been made yet.
They're big downloads
Roughly 200–250 MB per installer, because a complete runtime and the daemon ride along inside. That's before you download a single model.
First real-world builds
All three desktop builds are freshly built and run end to end. If something breaks on your setup, the boring detail helps most — what you ran it on, what you clicked, what happened instead.
Free, and there's no catch coming
No payment, no upsell later. TurboLLM is source-available and stays that way — the license is right there.
What happens to your details
Nothing is collected to download. Only if you join the iOS list are your name and address stored, so you can be told when a build exists. Not sold, not shared, deleted on request — the privacy policy spells it out.
Want it on iOS?
There's no iOS build yet. Leave your email and you'll get one message when there is — nothing else. The more people ask, the sooner it happens.